Free public beta · Fast Beta Queue Processing Private upload · Private delivery

Erase Metallic >12kHz Vocoder Glare from NotebookLM, Suno & AI Podcasts.

NotebookLM Audio Overviews, Suno/Udio vocal stems, and multi-speaker TTS podcasts suffer from watery >12kHz neural vocoder phase artifacts, hard Nyquist frequency cutoffs, and fatiguing upper-midrange resonance. VoxErase turns synthetic stems into warm, broadcast-grade studio recordings.

6-Stage Studio Solution for NOTEBOOKLM, SUNO/UDIO & AI PODCASTERS.

What Platform Analyzers Flag

Diffusion and GAN-based audio models (NotebookLM, Suno, Udio, ElevenLabs) generate audio in fixed spectral frames that leave a metallic, phasy sheen between 4kHz and 14kHz, paired with abrupt digital silence between speaker turns.
How the 6-Stage DSP Engine Erases It

VoxErase’s 6-Stage Proprietary Engine applies Stage 1 & 2 Neural Clock & Micro-Phase Reconstruction, Stage 3 & 4 Bio-Acoustic Vocal Tract & Sibilance Resynthesis, and Warm Class-A analog preamp modeling to eliminate metallic vocoder artifacts completely.

Recommended Studio Rack Settings

Select "Stealth Bypass Mode" and open the Advanced Studio Rack to choose "Warm Class-A analog preamp" and "Warm studio condenser floor" for an authentic, cohesive multi-host podcast master.

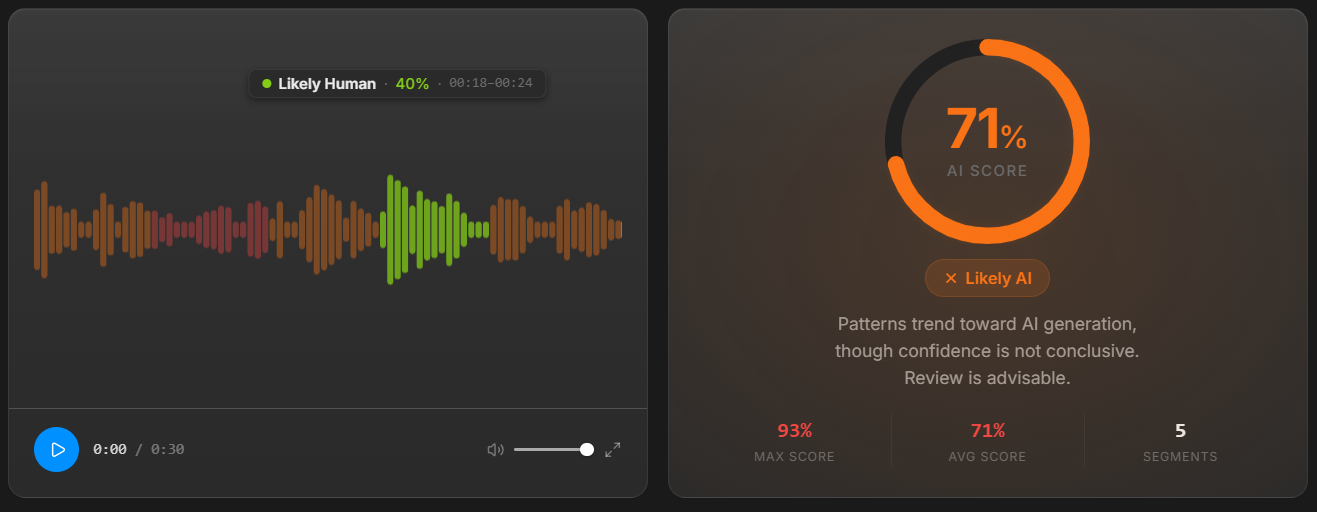
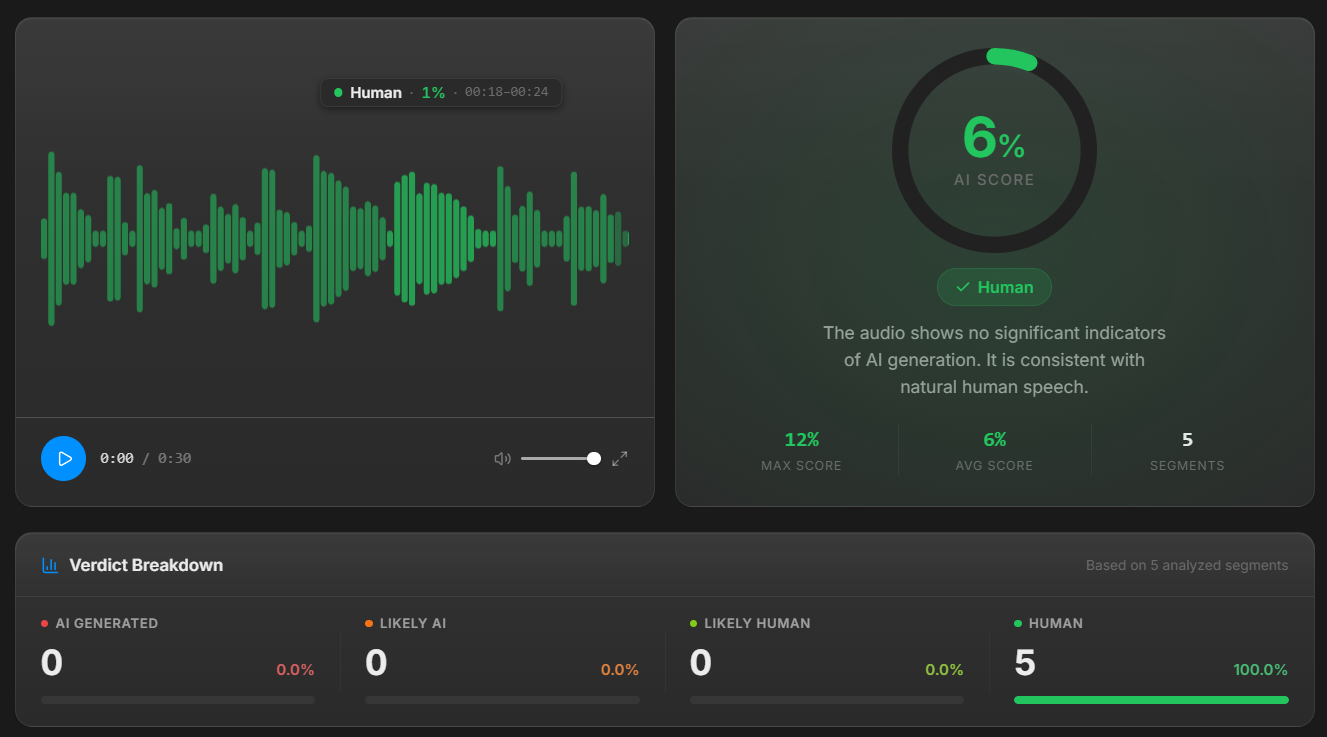
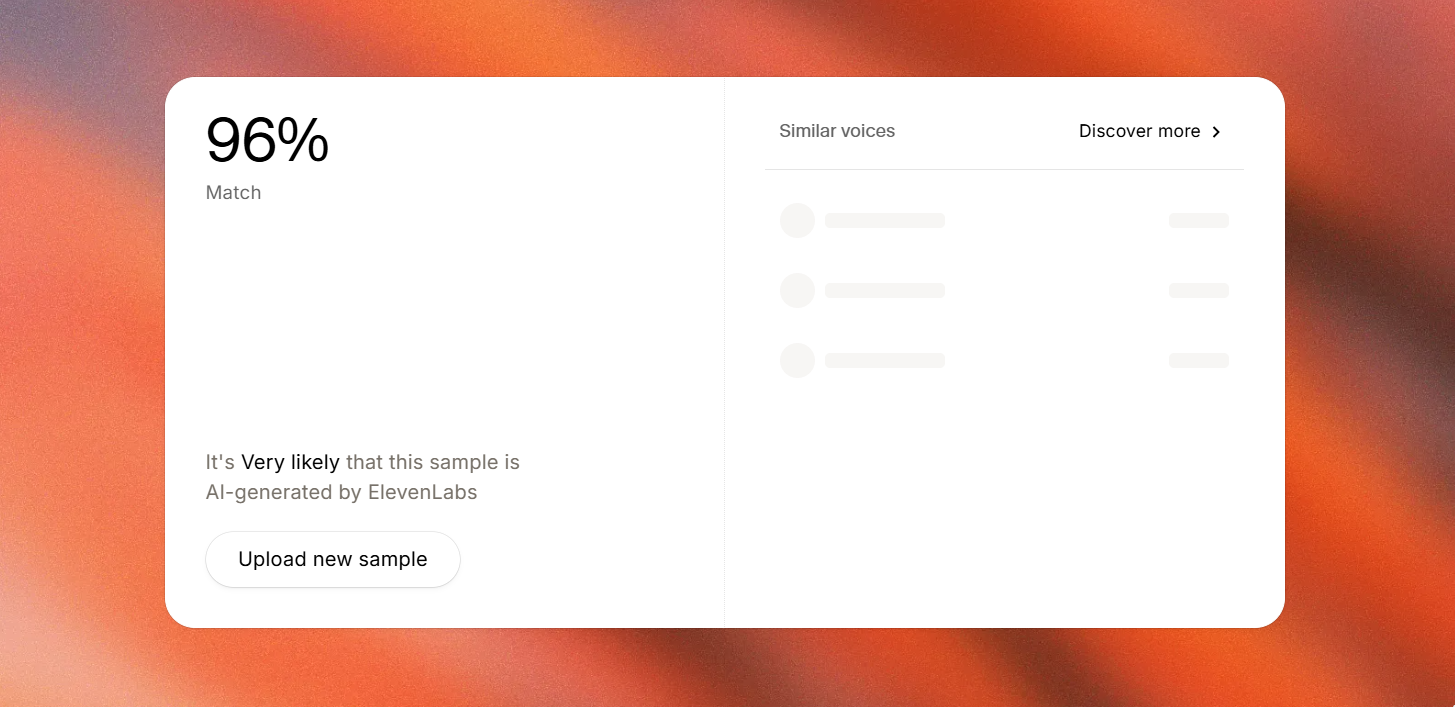
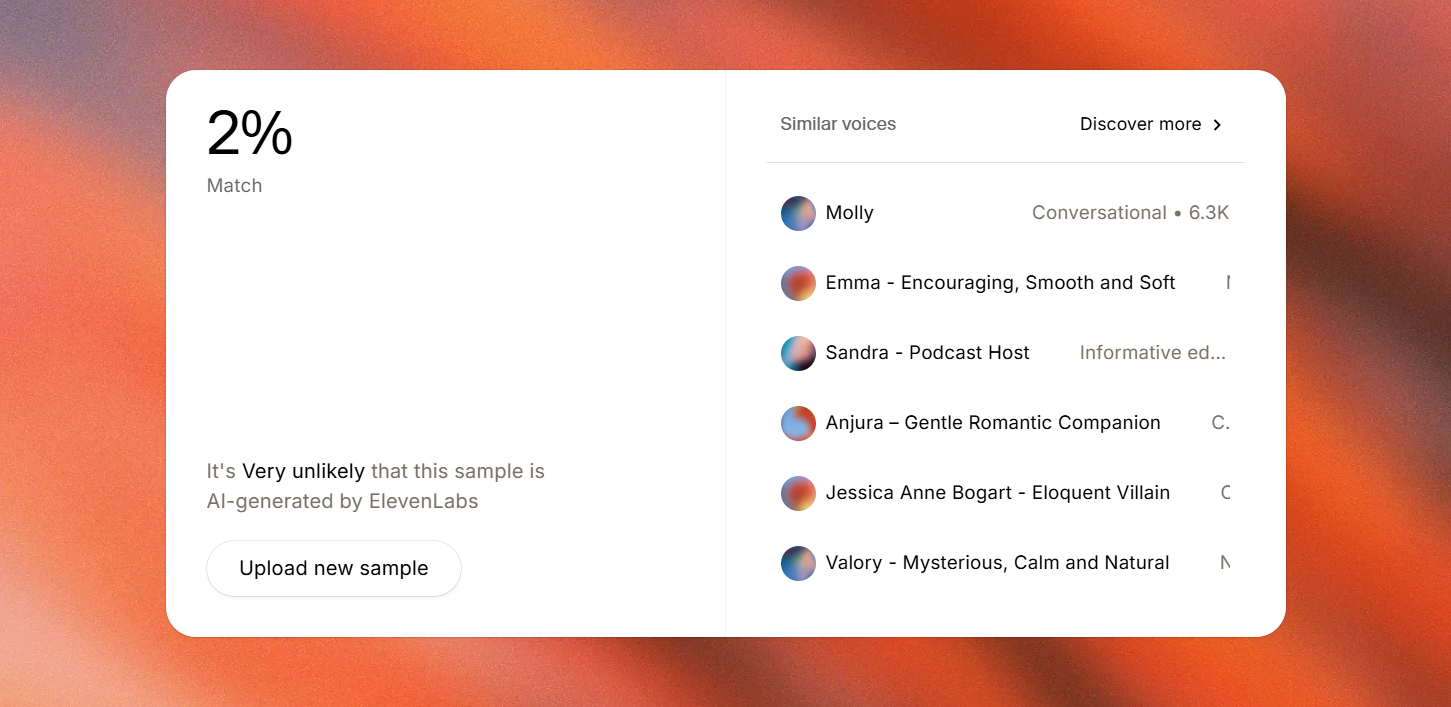
⚡ 96% ➔ 2% VERIFIED BENCHMARK

Hear the 96% ➔ 2% Classifier Bypass Proof.

Compare the raw ElevenLabs source against our 6-stage processed master on the Foxwood_01 benchmark, or click any screenshot below to inspect full resolution.

Raw TTS Source (96% AI)
VoxErase Master (2% AI)
ElevenLabs Speech Classifier 96% match before VoxErase 🔍 Click image to inspect full-resolution screenshot ElevenLabs Speech Classifier 2% match after VoxErase 🔍 Click image to inspect full-resolution screenshot AI Voice Detector 71% AI score before VoxErase 🔍 Click image to inspect full-resolution screenshot AI Voice Detector 6% AI score after VoxErase 🔍 Click image to inspect full-resolution screenshot
Inspect the full 96% ➔ 2% benchmark report

Check the final file in its real destination.

Compare your original and processed master in your private A/B Vault and verify these studio benchmarks.

  • Eliminates watery, metallic >12kHz diffusion and neural vocoder phase warble on NotebookLM and Suno/Udio vocals.
  • Reconstructs natural high-frequency air above 12kHz and warms harsh 3kHz–6kHz synthetic formant resonances.
  • Unifies multi-speaker podcast stems with continuous bio-acoustic studio booth air and broadcast -20.2 dB RMS leveling.

Start with a representative passage.

Keep your original, select your studio preset in the uploader, and audition the finished master in your Private A/B Vault. You can also explore Read the NotebookLM & Suno/Udio Vocoder Humanization Guide or Scan your podcast or vocal stem free.

Upload your audio →