ORIGINAL96%match→PROCESSED2%match
Numbers shown in the supplied classifier screenshots for this test example.
One source recording, one processed output, two sets of third-party screenshots. Here is what can be observed, what remains unknown, and how to evaluate your own voiceover.
Play the supplied before-and-after recordings. This is one example, not a promise of the same outcome for every source file.
A roughly 31-second AI-generated source recording and its processed output, provided by VoxErase.
Original sample could not load. Please try again later.
Processed sample could not load. Please try again later.
The audio files are real. The decorative waveforms are illustrative and do not plot their measured signals.
A verified narration pair has not been published yet.
Waveforms are illustrative interface art. More real examples will appear only when source-matched audio is available.
A verified long-form pair has not been published yet.
Waveforms are illustrative interface art. More real examples will appear only when source-matched audio is available.
These screenshots show point-in-time outputs from two third-party tools. Detector scores depend on the file, service and test conditions; neither result predicts other recordings.
Numbers shown in the supplied classifier screenshots for this test example.
Overall AI scores shown in the supplied five-segment scan screenshots.
Format and duration read from the supplied audio files. No mastering certification is implied.
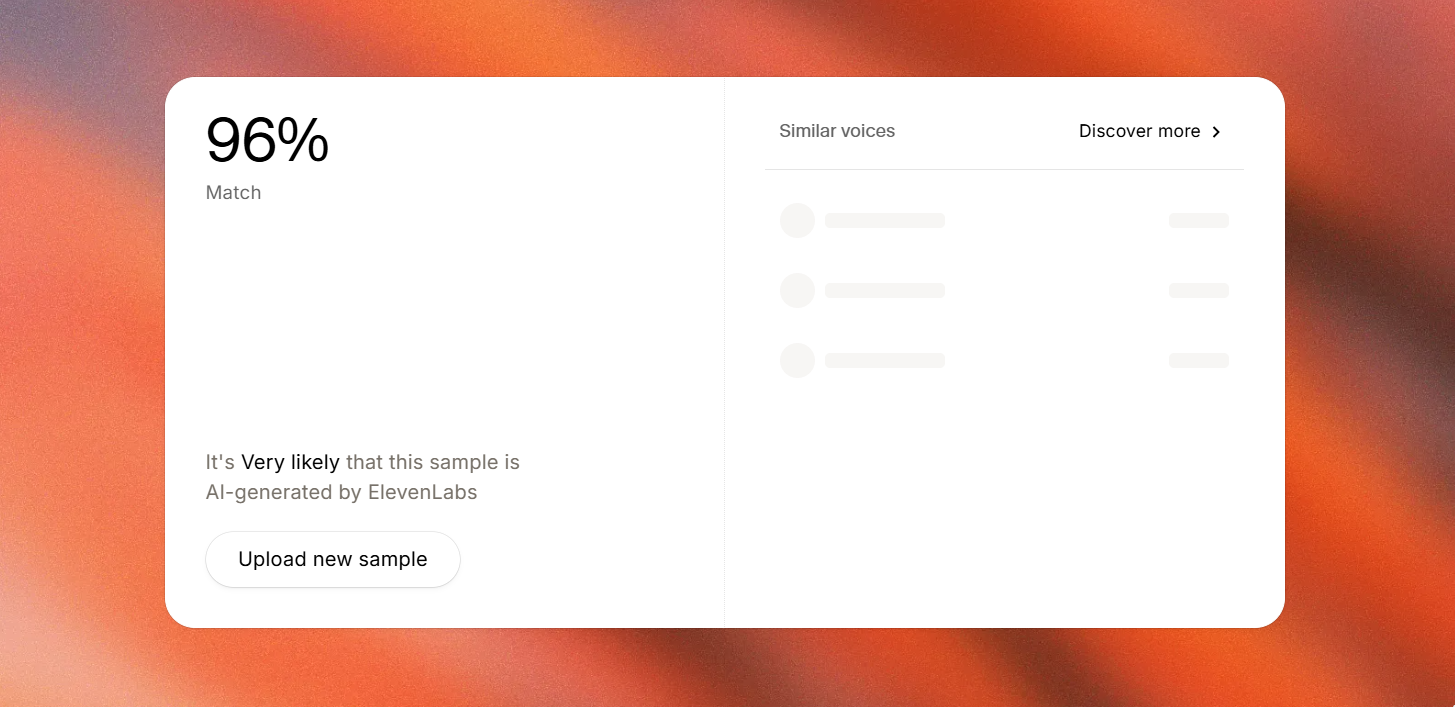
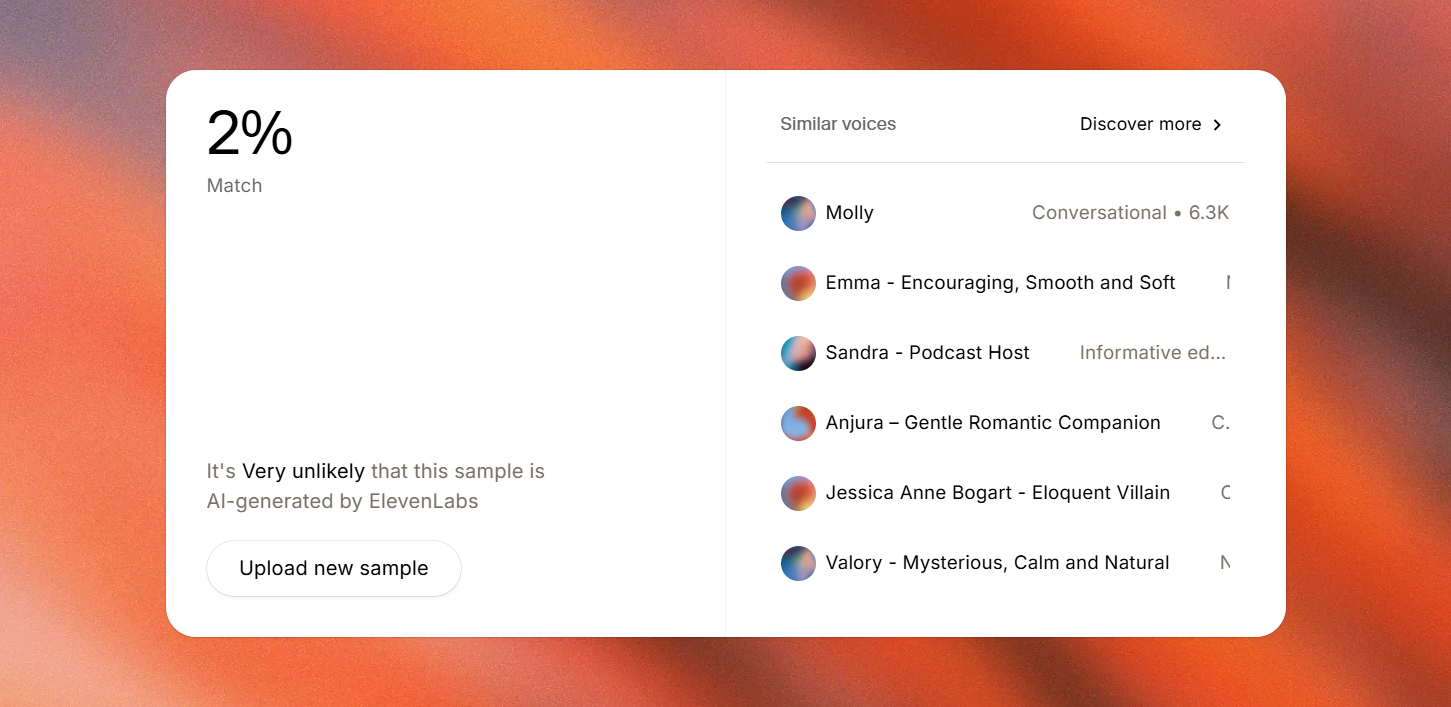
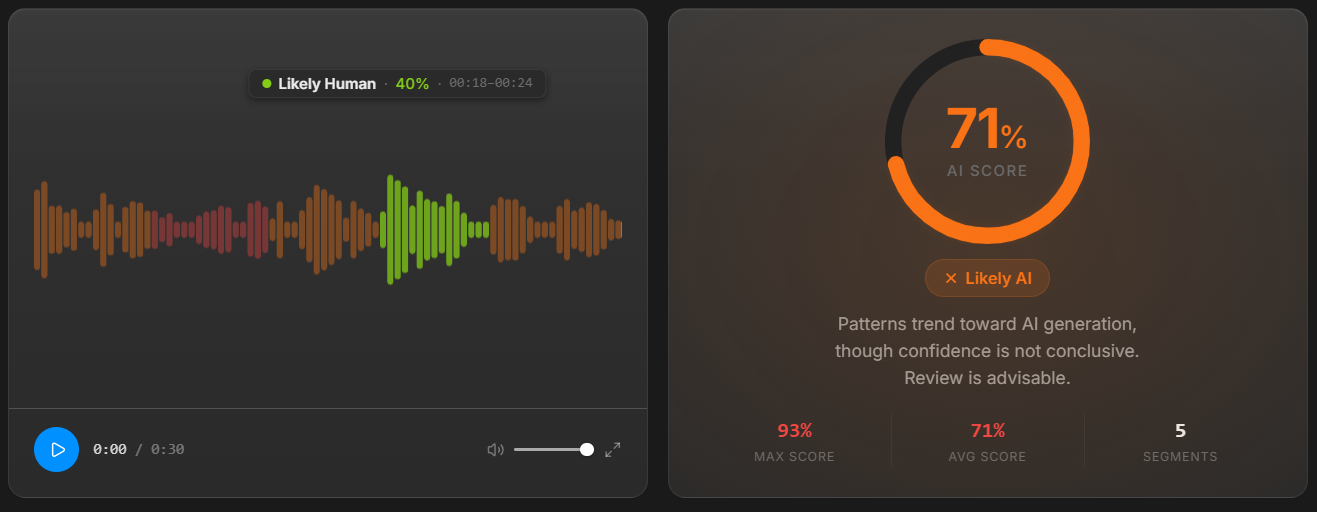
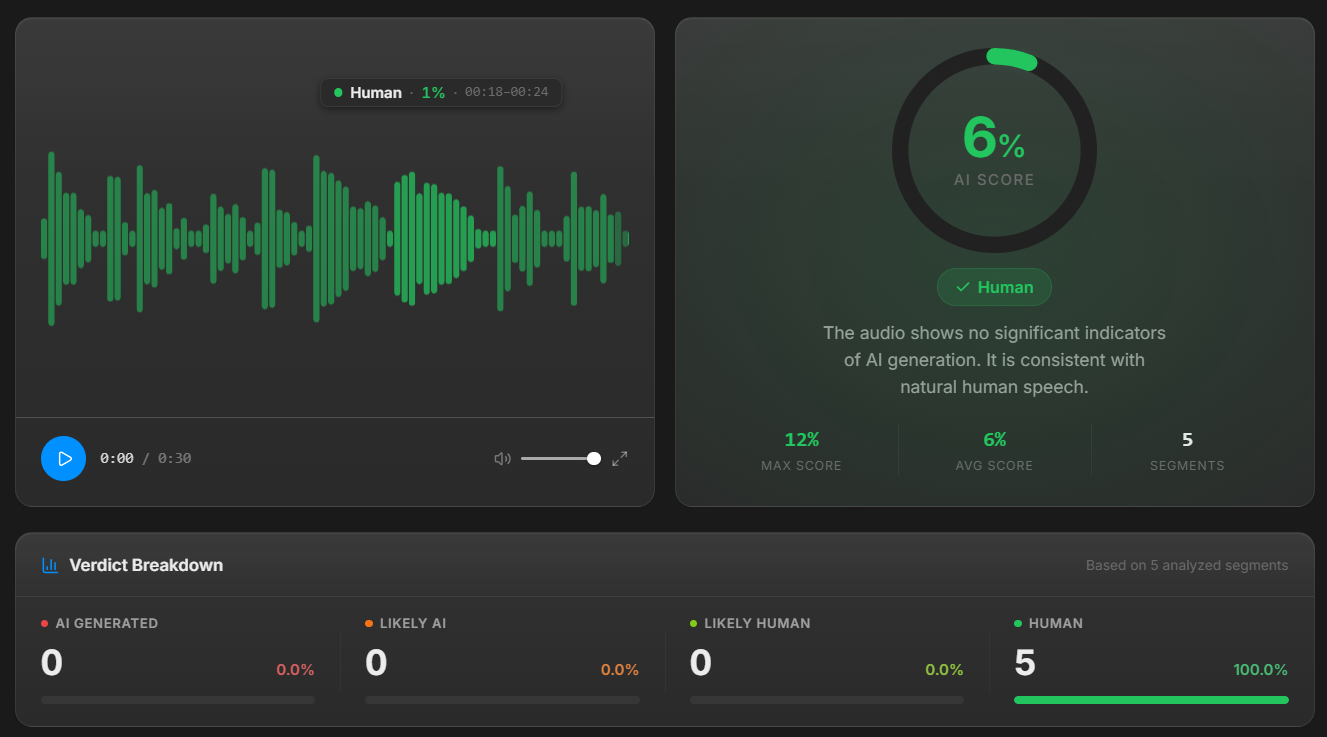
Screenshots and audio were supplied for this example. VoxErase is independent of both detector providers. These tools are not a universal test of human origin, provenance watermarks, or platform acceptance.
The original WAV is approximately 31 seconds; the processed MP3 is approximately 31 seconds. In the supplied ElevenLabs Speech Classifier screenshots, the match shown for this sample changes from 96% before to 2% after. In the supplied AI Voice Detector screenshots, the overall AI score changes from 71% to 6%.
Those are point-in-time outputs from two tools, not independent replication or a predicted result. The recordings also differ in container and encoding. Do not treat the number change as proof of human origin, watermark removal, or acceptance by any publisher.
A speech classifier may respond to timing, spectral texture, phase behavior, codec artifacts and other acoustic features. Our described multi-stage DSP workflow addresses several of those dimensions, including Bark-scale spectral shaping, pause cadence elasticity, sample-clock resampling and allpass phase dispersion. We do not disclose parameters or attribute this sample’s score change to a single stage.
Processing can also introduce unwanted artifacts. That is why the delivered file receives quality review and should be evaluated by ear. A low score on one detector is not a universal test of authorship.
Keep the original. Listen through matched sections of the source and finished files at the same perceived level. Note any lost consonants, altered pacing, pumping, metallic tone or noise.
If you use a detector, test both files with the same service and note its version or date, file duration and output type. For a provider watermark question, use that provider’s supported verification process. A classifier score cannot certify provenance.
Explore the service, read how intake and delivery work, or submit your first beta file.